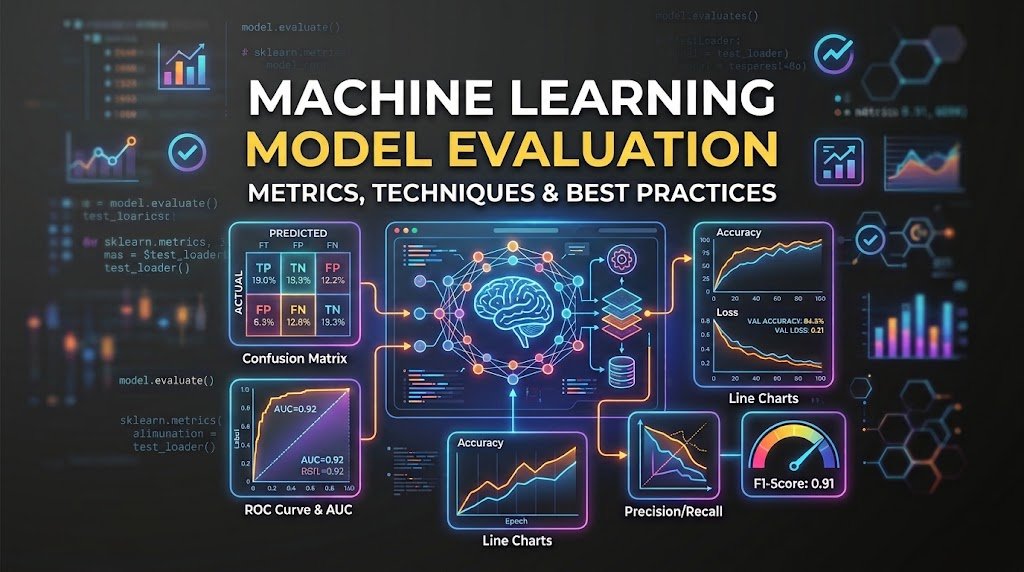
The goal of machine learning models is to identify patterns in data and use them to make predictions or uncover relationships. However, building a model is only part of the process. It’s also important to determine how well the model performs and whether its results are reliable. This is known as model evaluation, a procedure that helps assess the quality and effectiveness of a machine learning model.
Model evaluation involves comparing a model’s predictions or outputs against appropriate measures of performance. For supervised learning, this often means comparing predicted outcomes with known results from a separate test dataset. This helps determine whether the model has learned helpful patterns that can be applied to new data.
The way a model is evaluated depends on the type of machine learning task. Classification models predict categories, such as whether an email is spam or whether a customer is likely to leave a service. One common evaluation method is accuracy, which measures the proportion of predictions that are correct. However, accuracy does not always provide a complete picture. If a dataset contains many more examples of a category than another, a model could achieve high accuracy while performing poorly at identifying the less common category.
Other classification metrics can provide a more detailed assessment. Precision measures how many of the cases predicted as positive are actually positive, while recall measures how many of the actual positive cases the model successfully identifies. For example, in a system designed to detect fraudulent transactions, precision helps assess how many flagged transactions are genuinely deceitful, while recall indicates how much of the fraud is being detected. The appropriate balance depends on the consequences of false alarms and missed cases.
Unsupervised learning models can also be evaluated, although this is often more challenging because the data does not contain predefined target outcomes. Clustering models, for instance, group similar observations together. Their evaluation may consider how closely related the observations within each cluster are and how clearly each is separated. The best approach depends on the algorithm and what the model is intended to achieve.
A key consideration in model evaluation is ensuring that the results reflect how the model will perform in practice. A model should not be assessed solely using the same data it learned from, as this gives an overly optimistic impression of its performance. Instead, separate test data can provide a more realistic assessment. Comparing different models using consistent evaluation methods also helps identify which approach is most suitable for a particular task. Ultimately, an effective model is not necessarily the one with the highest score for a single metric, but the one that meets the requirements of its application.
Oracle Machine Learning supports model evaluation as part of its model development process. Within Oracle Machine Learning for SQL, models can be assessed using metrics suited to their tasks. Say, classification models can be evaluated using confusion matrices, precision and recall, while regression models can be assessed using measures such as RMSE. These results help users compare model performance and determine whether a model is suitable for further use.
Overall, model evaluation is an essential step in developing reliable machine learning systems. By using the right metrics and testing models on relevant data, organizations can better understand the strengths and limitations of their predictions. This helps them select models that not only perform well during development, but also provide dependable results when applied to real world problems.